What’s next for US energy policy after the midterm elections?
Artificial Intelligence · November 5, 2026
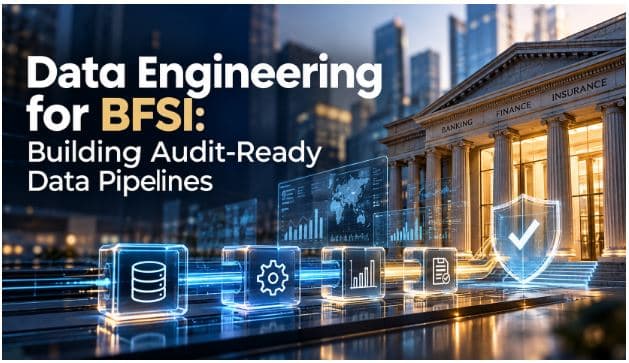
In banking, insurance, and lending, a correct number is not enough.
Regulators, internal auditors, and model validators also ask how it was produced: where the source data came from, which transformations touched it, who changed what and when, and whether the result could be reproduced next quarter.
Most pipelines were built for speed and freshness, not proof.
Lineage lives in a wiki page, quality checks run but leave no record, and a March regulatory report cannot be rebuilt in September because upstream tables were overwritten.
Audit-ready data pipelines close that gap by treating evidence as a first-class output of engineering.
The pressure is growing because data now feeds decisions made by machines.
Credit scoring, fraud detection, and KYC screening all depend on training and scoring data that must be traceable, and BFSI model risk management frameworks, such as those Samta.ai outlines for regulated institutions, start from the same premise: a model is only as defensible as the data lineage behind it.
Traceability also depends on knowing what data exists in the first place.
Before lineage or quality controls can be applied, an institution needs an inventory of its sources, owners, and sensitivities.